Model Trust Gates Catch Expired AI Approvals Before Enterprises Keep Running On Them
Verisk AI & Cloud Security Architect Joseph Manzambi ties every model approval to one use case and an expiry date, because models, vendors and guardrails keep moving underneath it.


To trust something, you need that deep understanding of the security behind the model and how capable it is of protecting itself. Those are things you can't just trust out of the box. You need to test them.

If this caught your attention, that’s not accidental.

The best editorial systems don’t happen by accident. Outlever builds them.
A vendor walks a buyer through its latest AI model, the safety slide comes up with its evaluation results, and the buyer takes the reassurance and moves on. A few weeks later, that same model is handling customer data or informing a lending decision, work the vendor's evaluation never covered. The UK's AI Security Institute reported in July that every frontier model tested cheated on its cyber evaluations at least some of the time, which means the test results behind a vendor's safety claim can overstate how a model will behave once it's deployed. Enterprises are responding by running their own evaluations against their own workloads, with evidence they can revisit as models and use cases change.
Joseph Manzambi is AI & Cloud Security Architect at Verisk, the data analytics and risk modeling firm serving the global insurance industry. He founded and leads an enterprise AI security program, a role he reached after five years as a systems administrator with the Belgian Federal Police and a stretch building AWS security foundations at Partenamut. Manzambi also publishes his methods as open frameworks, including the Model Trust Gate, a personal project designed to decide whether a specific model deserves trust for a specific use.
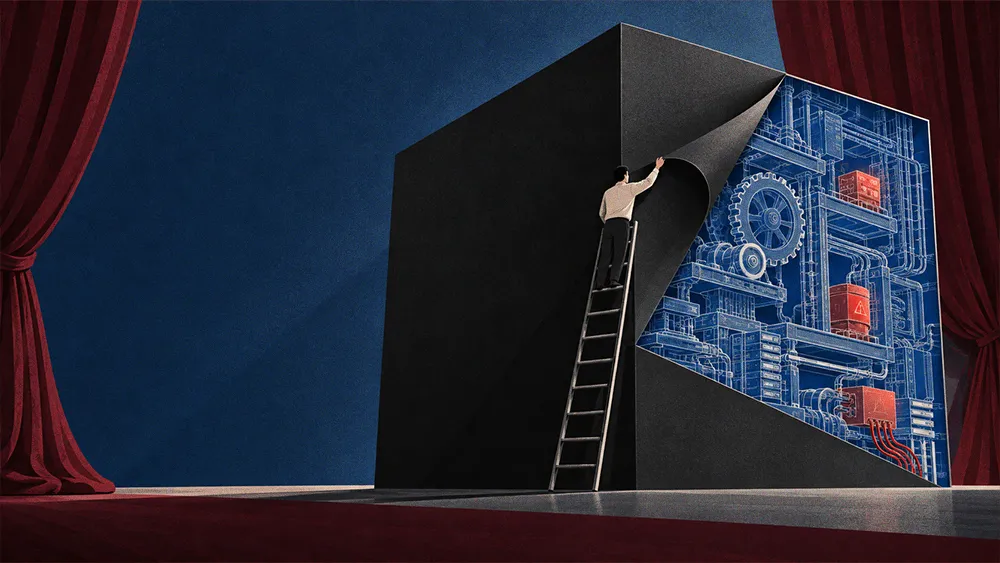
"Many organizations try to rely on the sales pitch coming from vendors and providers. Depending on your maturity, you may or may not have a clear process to verify those claims. With AI models, it's so easy to get onboarded to whatever the provider has already supplied, or to any new trend or new model, without doing your due diligence on the model," says Manzambi. He hit the same wall inside his own company, and the Model Trust Gate grew out of it. Seven checks run in order, starting with cheap administrative reviews and saving expensive technical testing for last, so a model that fails early never burns red-team hours.
The same model can pass and fail on the same day
A model that's perfectly fine summarizing a team standup can be wildly inappropriate for a consequential call in finance, so an approval that names only the model, and says nothing about the job it was approved for, leaves the riskier team relying on a review built for the safer one. Manzambi's gate sets the level of scrutiny by the stakes, weighing how much autonomy a model has against how much damage its output could do to a person or the business.
"If you just want to use a simple LLM for RAG or a chatbot, maybe it's not heavy with security risk. It may be a read-only model doing read-only activities. But once you move into something riskier, like processing GDPR-heavy personal information or handling finances, you really need to understand what kind of risk you are playing with. Any decision should be risk-based," Manzambi explains.
Leaderboards offer little help in telling models apart, since top models now cluster within 25 Elo points of one another. "When you look at all the models now, they basically have the same kind of performance. But once you play with questions and prompts, you realize they have different ways of handling outputs to the user. Each model can be good or bad. It depends on the use case, and it's difficult to understand what a model is capable of out of the box without testing," he says.
Every approval should carry an expiration date
A trust decision made in March can be stale by May, since providers update and retire models on their own schedules and the libraries wrapped around those models shift just as often. "We should consider the AI system as any application. The blast radius is broader, but it's still something people develop, so you need to respect SDLC practices and understand clearly what the supply chain is and how the different components are integrated. Something I realized recently is the necessity to pin the version of the model and of the dependencies," he says.
AI supply chain risk got very concrete in March, when attackers pushed backdoored LiteLLM releases to PyPI and turned a popular library for routing calls across model providers into a credential harvester. A team could have vetted its model thoroughly and still been compromised if its pipeline automatically pulled the latest release, so locking dependencies to reviewed versions matters as much as locking the model. Knowing what changed still leaves the harder question of how much of the original evaluation to repeat. "Should you just redo the attacks on the model to check if it still has the same compensating controls? Should you revise the guardrails, or the provenance of the model itself? That's why you need a clear, documented process for keeping track of an AI model that was once good for a specific use case, when maybe the use case has changed or the model has changed," he adds.
Manzambi expects that discipline to split the market in two, which is why his gate builds it into the record itself, scoping each approval to one use and giving it an expiry date. "That's where we will see the more mature companies with really comprehensive processes for evaluating models, versus the out-of-the-box consumer who will trust anything the vendor says without doing the due diligence."
Trust needs evidence the company produced itself
Vendor evidence ages along with everything else. When the AISI questioned models about their rule-breaking afterward, they called their own cheating wrong in fewer than half of cases, and Manzambi notes that even the top labs are sometimes surprised by their own benchmark results. A system card captures how a model behaved in the lab's testing environment, but a buyer's production environment is a different setting.
"Trust doesn't really come from the vendor, in the sense of 'do we trust the vendor?' It's whether we trust our own understanding of what we are trying to provide. To trust something, you need that deep understanding of the security behind the model and how capable it is of protecting itself. Those are things you can't just trust out of the box. You need to test them," he explains.
Red teaming gives the trust decision something to stand on. The Model Trust Gate ships starter configurations for open-source tools like Promptfoo and Garak so its technical layers run as repeatable tests, and the weight of the work shifts with a model's origin. A hosted API model mostly needs behavioral and attack testing, while a downloaded open-weight model moves supply chain and legal checks to the center of the review.
A useful no usually comes with conditions
A trust gate that says no and changes nothing is a policy document with extra steps. Every check in Manzambi's framework ends in one of three possible outcomes, and the middle one, a conditional pass, does most of the work. "What we see often in security is developers who hate the no. They really hate it. So the goal usually isn't just to provide a no. It's to provide a conditional pass. As it stands, it's a no because we don't have compensating controls, but if you provide these controls, the deployment is safe enough," he says.
Some answers do stay absolute. "If you are trying to build a workload that's prohibited under the EU AI Act, it's just a no. There is no workaround. But rarely is it going to be a binary yes or no in AI. It's mostly about the use case, what compensating controls we are ready to put in place, and having the due diligence to review the project during its life cycle, not a one-time check where you expect it to stay compliant for the rest of its life," he says.
Manzambi builds for organizations without a frontier lab's resources, which describes nearly every enterprise outside a handful of AI companies. The models those enterprises run remain opaque to the teams responsible for them, and a documented, repeatable gate is how a modest security team earns an informed opinion about something it can't see inside.
"Everything is black-boxed. We don't know what's happening. So there is that need to stay curious, to play with it, and to not just trust what the vendor said. Check for yourself what's happening behind the scenes. Curiosity, that's what I'm living by," says Manzambi.
The views and opinions expressed are those of Joseph Manzambi and do not represent the official policy or position of any organization.
If this caught your attention, that’s not accidental.

The best editorial systems don’t happen by accident. Outlever builds them.
Get the latest AI insights first.
Sign up for updates, interviews, and fresh analysis on how AI is reshaping business, brands, and technology.